Most of the queries that artificial intelligence systems answer will never touch the most expensive chip in the building. Intel’s argument, made in a release on October 17, is that a large share of them should not have to.
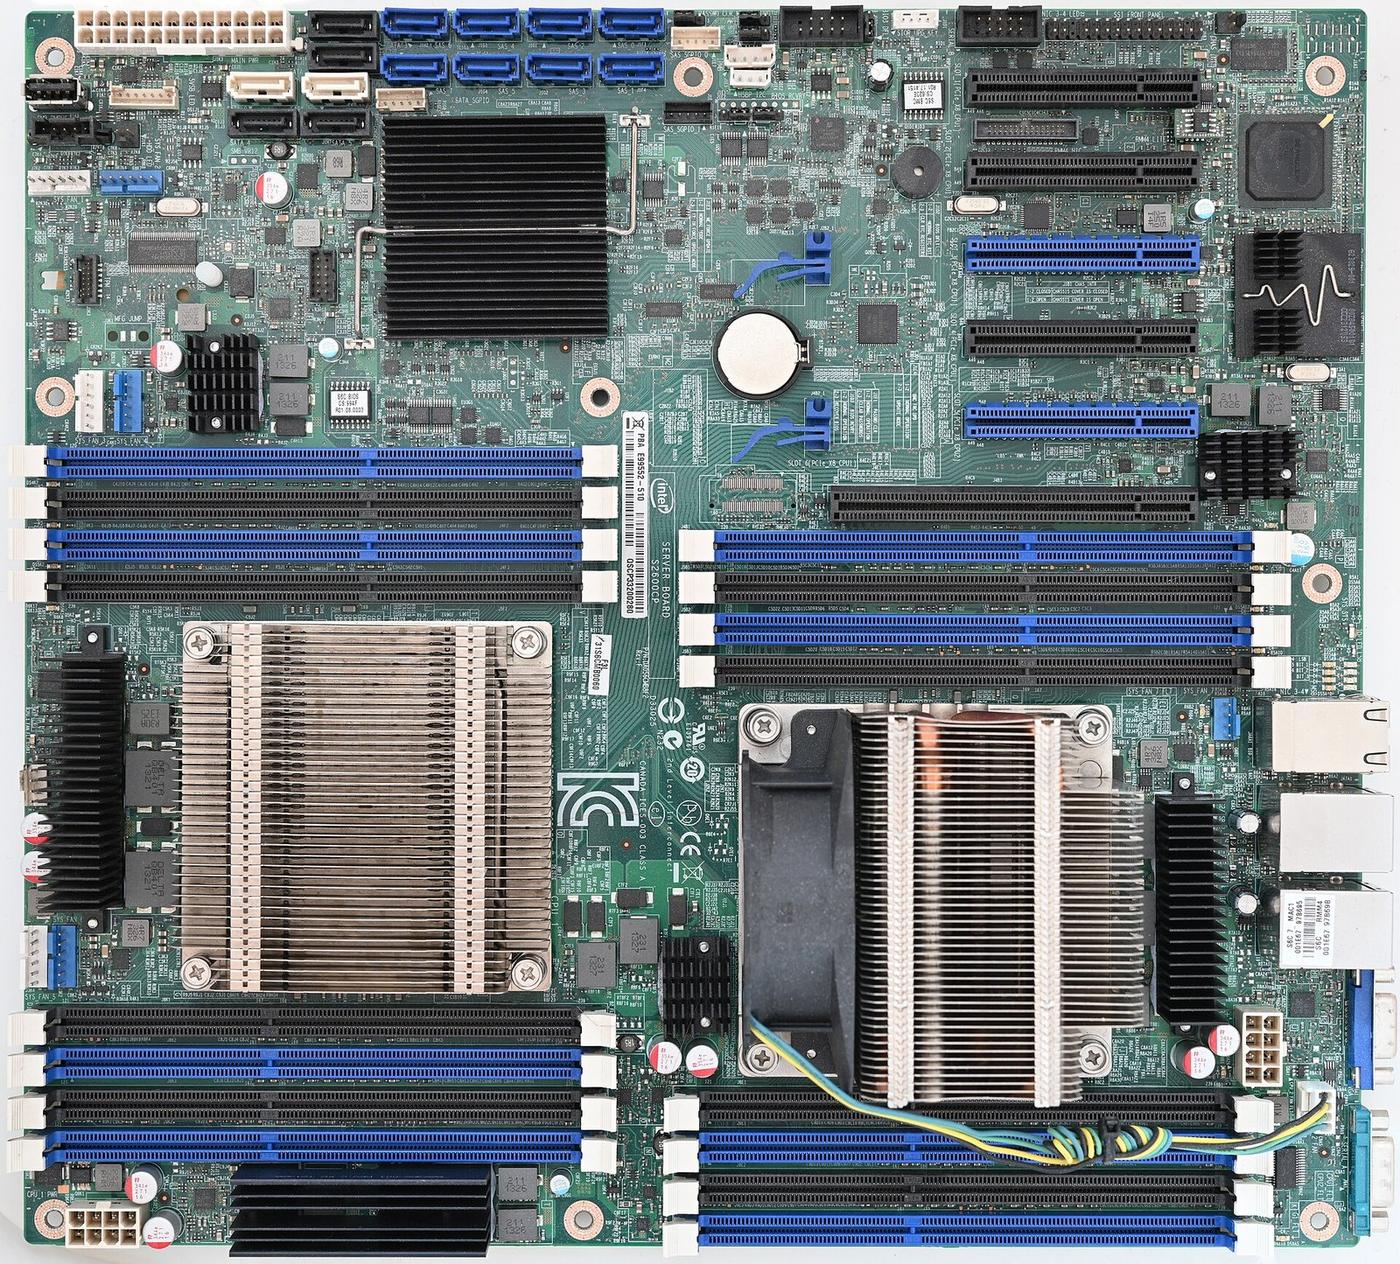
The company published a package of software optimizations for running AI inference on Xeon processors, aimed at companies that already own racks of CPU servers. According to THE ELEC, which reported the release in Korea, the pitch is throughput on hardware customers have bought rather than a new accelerator they would have to queue for.
Intel has made versions of this argument before. What has changed is the workload. Inference for a chatbot answering one question at a time is dominated by the cost of moving data in and out of memory, and a graphics processor that can multiply matrices faster than a CPU still spends most of its time waiting when the batch is small. A server processor with a wide memory subsystem and a large cache is inefficient in the way that a delivery van is inefficient next to a truck: it carries less, but it leaves more often.
The company’s hardware already includes matrix instructions, introduced with its Sapphire Rapids generation, that handle the arithmetic that inference needs. The software layer is where the argument gets won or lost, because a model that runs well on one framework may run badly on another, and the engineers who deploy these systems choose libraries before they choose silicon. Intel has built its tools around converting models trained elsewhere into a form its chips execute efficiently, and around squeezing more work out of each core when a company runs many small models instead of one large one.
The commercial logic is straightforward. Intel’s share of data center revenue has been eroded by competitors selling accelerators, and its share of the general purpose server market has been eroded by Advanced Micro Devices. Selling software that improves the utilization of machines already installed is a way to defend an installed base without asking customers for capital. Every server that stays in service for another two years is a server that is not replaced by something else.
There is a second argument, about where inference is going. Agentic systems, the ones that plan a task and call tools in sequence, generate many short requests rather than one long one. A workflow that checks an inventory system, drafts a message and books a slot may make a dozen calls to a model, each of them small. Small calls are bad for accelerators, which are built to process large batches, and good for processors with low latency per request and enough memory to hold a model that has been compressed to fit.
Whether customers accept the framing is a separate question. The companies with the largest inference bills have already built their stacks around accelerators, and the engineers who run them measure cost per token on hardware they know. A software release that claims a throughput gain has to be reproduced on real traffic, with real models, before it changes a purchasing decision. Intel’s own benchmarks will be read with the skepticism that any vendor’s numbers attract, particularly by customers who remember earlier generations of optimization claims that did not survive contact with production.
The economics of the alternative are also moving. Accelerator supply has improved, rental prices for the largest instances have fallen in some markets, and the buyers who signed multi-year commitments are now looking at utilization rates that are lower than they projected. When capacity is no longer scarce, the case for using hardware you already own gets stronger, and the case for buying more of the fastest hardware gets weaker.
The limits are real. A model with hundreds of billions of parameters does not fit comfortably on a server processor, and the memory bandwidth of a CPU socket is a fraction of what a high-bandwidth accelerator provides. Intel is not arguing that CPUs replace accelerators for training, or for the largest models. It is arguing that a large volume of production traffic consists of smaller models, retrieval steps, classification, and the guardrails that sit around a model and check what it says, and that this traffic belongs on the hardware that is already in the rack.
That argument has an organizational dimension inside Intel as well. The company sells processors, networking and foundry capacity, and its software teams have historically been organized around product lines rather than around customer workloads. A package that spans Xeon, its accelerators and its developer tools is an attempt to sell a stack rather than a component, which is what its competitors have done more effectively.
For the buyers, the decision will come down to a measurement they can run themselves: how many requests per second per rack, at what latency, with what accuracy after quantization. Those numbers are available to any customer with a workload and a week of engineering time, which is why the software release matters more than the announcement around it. Intel’s case will be settled in other companies’ data halls, one benchmark at a time.